Ways To Boost The Value of Testers Who Don’t Code
7 comments Posted by Eric Jacobson at Wednesday, February 10, 2016Despite the fact that most Automation Engineers are writing superficial automation, the industry still worships automation skills, and for good reasons. This is intimidating for testers who don’t code, especially when finding themselves working alongside automation engineers.
Here are some things, I can think of, testers-who-don’t-code can do to help boost thier value:
- Find more bugs - This is one of the most valued services a tester can provide. Scour a software quality characteristics list like this to expand your test coverage be more aggressive with your testing. You can probably cover way more than automation engineers in a shorter amount of time. Humans are much better at finding bugs than machines. Finding bugs is not a realistic goal of automation.
- Faster Feedback – Everybody wants faster feedback. Humans can deliver faster feedback than automation engineers on new testing. Machines are faster on old testing (e.g., regression testing). Report back on what works and doesn’t while the automation engineer is still writing new test code.
- Give better test reports – Nobody cares about test results. Find ways to sneak them in and make them easier to digest. Shove them into your daily stand-up report (e.g., “based on what I tested yesterday, I learned that these things appear to be working, great job team!”). Give verbal test summaries to your programmers after each and every test session with their code. Give impromptu test summaries to your Product Owner.
- Sit with your users – See how they use your product. Learn what is important to them.
- Volunteer for unwanted tasks – “I’ll stay late tonight to test the patch”, “I’ll do it this weekend”. You have a personal life though. Take back the time. Take Monday off.
- Work for your programmers - Ask what they are concerned about. Ask what they would like you to test.
- What if? – Show up at design meetings and have a louder presence at Sprint Planning meeting. Blast the team with relentless “what if” scenarios. Use your domain expertise and user knowledge to conceive of conflicts. Remove the explicit assumptions one at a time and challenge the team, even at the risk of being ridiculous (e.g., what if the web server goes down? what if their phone battery dies?).
- Do more security testing – Security testing, for the most part, can not be automated. Develop expertise in this area.
- Bring new ideas – Read testing blogs and books. Attend conferences. Tweak your processes. Pilot new ideas. Don’t be status quo.
- Consider Integration – Talk to the people who build the products that integrate with your product. Learn how to operate their product and perform integration tests that are otherwise being automated via mocks. You just can’t beat the real thing.
- Help your automation engineer – Tell them what you think needs to be automated. Don’t be narrow-minded in determining what to automate. Ask them which automation they are struggling to write or maintain, then offer to maintain it yourself, with manual testing.
- Get visible – Ring a bell when you find a bug. Give out candy when you don’t find a bug. Wear shirts with testing slogans, etc.
- Help code automation – You’re not a coder so don’t go building frameworks, designing automation patterns, or even independently designing new automated checks. Ask if there are straight forward automation patterns you can reuse with new scenarios. Ask for levels of abstraction that hide the complicated methods and let you focus on business inputs and observations. Here are other ways to get involved.
Testers Are Never Done - Like Scientists
4 comments Posted by Eric Jacobson at Friday, August 21, 2015I’m a Dr. Neil deGrasse Tyson fanboy. In this video, he pokes fun of a common view of scientists. A view that when scientists think they’ve figure something out, they stop investigating and just sit around, proud of themselves. Neil says, “[scientists] never leave the drawing board”. They keep investigating and always embrace new evidence, especially when it contradicts current theories.
In other words, a scientist must trade closure for a continued search for truth. “Done” is not the desired state.
As a tester, I have often been exhausted, eager to make the claim. “it works…my job here is done”. And even when faced with contradicting evidence, I have found myself brushing it away, or hoping it is merely a user problem.
Skilled testers will relate. Test work can chew us up and spit us out if we don’t have the right perspective. Don’t burden yourself by approaching test work as something you are responsible for ending.
If You Interrupt Testing, It Will Cost Us 2 Lost Bugs
3 comments Posted by Eric Jacobson at Wednesday, April 22, 2015Look at your calendar (or that of another tester). How many meetings exist?
My new company is crazy about meetings. Perhaps it’s the vast numbers of project managers, product owners, and separate teams along the deployment path. It’s a wonder programmers/testers have time to finish anything.
Skipping meetings works, but is an awkward way to increase test time. What if you could reduce meetings or at least meeting invites? Try this. Express the cost of attending the meeting in units of lost bugs. If you find, on average, about 1 bug per hour of testing, you might say:
“Sure, I can attend your meeting, but it will cost us 1 lost bug.”
“This week’s meetings cost us 9 lost bugs.”
Obviously some meetings (e.g., design, user story review, bug triage) improve your bug finding, so be selective when choosing to declare the bugs lost cost.
Last week I started testing an update to a complex legacy process. At first, my head was spinning (it still kind of is). There are so many inputs and test scenarios...so much I don’t understand. Where to begin?
I think doing something half-baked now is better than doing something fully-baked later. If we start planning a rigorous test based on too many assumptions we may not understand what we’re observing.
In my case, I started with the easiest tests I could think of:
- Can I trigger the process-under-test?
- Can I tell when the process-under-test completes?
- Can I access any internal error/success logging for said process?
- If I repeat the process-under-test multiple times, are the results consistent?
If there were a spectrum that showed a focus between learning by not manipulating and learning by manipulating something-under-test, it might look like this:
My tests started on the left side of the spectrum and worked right. Now that I can get consistent results, let me see if I can manipulate it and predict its results:
- If I pass ValueA to InputA, do the results match my expectations?
- If I remove ValueA from InputA, do the results return as before?
- If I pass ValueB to InputA, do the results match my expectations?
As long as my model of the process-under-test matches my above observations, I can start expanding complexity:
- If I pass ValueA and ValueB to InputA and ValueC and ValueD to InputB, do the results match my expectations?
- etc.
Now I have something valuable to discuss with the programmer or product owner. “I’ve done the above tests. What else can you think of?”. It’s much easier to have this conversation when you’re not completely green, when you can show some effort. It’s easier for the programmer or product owner to help when you lead them into the zone.
That worst is over. The rest is easy. Now you can really start testing!
Sometimes you just have to do something to get going. Even if it’s half-baked.
Getting Manual Testers Involved in Automation
2 comments Posted by Eric Jacobson at Friday, March 27, 2015Most of the testers at my new company do not have programming skills (or at least are not putting them to use). This is not necessarily a bad thing. But in our case, many of the products-under-test are perfect candidates for automation (e.g., they are API rich).
We are going through an Agile transformation. Discussions about tying programmatic checks to “Done” criteria are occurring and most testers are now interested in getting involved with automation. But how?
I think this is a common challenge.
Here are some ways I have had success getting manual testers involved in automation. I’ll start with the easiest and work my way down to those requiring more ambition. A tester wanting to get involved in automation can:
- Do unit test reviews with their programmers. Ask the programmers to walk you through the unit tests. If you get lost ask questions like, “what would cause this unit test to fail?” or “can you explain the purpose of this test at a domain level?”.
- Work with automators to inform the checks they automate. If you have people focused on writing automated checks, help them determine what automation might help you. Which checks do you often repeat? Which are boring?
- Design/request a test utility that mocks some crucial interface or makes the invisible visible. Bounce ideas off your programmers and see if you can design test tools to speed things up. This is not traditional automation. But it is automation by some definitions.
- Use data-driven automation to author/maintain important checks via a spreadsheet. This is a brilliant approach because it lets the test automater focus on what they love, designing clever automation. It lets the tester focus on what they love, designing clever inputs. Show the tester where the spreadsheet is and how to kick off the automation.
- Copy and paste an automated check pattern from an IDE, rename the check and change the inputs and expected results to create new checks. This takes 0-to-little coding skills. This is a potential end goal. If a manual tester gets to this point, buy them a beer and don’t push them further. This leads to a great deal of value, and going further can get awkward.
- Follow an automated check pattern but extend the framework. Spend some time outside of work learning to code.
- Stand up an automation framework, design automated checks. Support an Agile team by programming all necessary automated checks. Spend extensive personal time learning to code. Read books, write personal programs, take online courses, find a mentor.
You must really be a sucky tester.
I’m kidding, of course. There may be several explanations as to why an excellent tester like yourself is not finding bugs. Here are four:
- There aren’t any bugs! Duh. If your programmers are good coders and testers, and perhaps writing a very simple Feature in a closely controlled environment, it’s possible there are no bugs.
- There are bugs but the testing mission is not to find them. If the mission is to do performance testing, survey the product, determine under which conditions the product might work, smoke test, etc., it is likely we will not find bugs.
- A rose by any other name… Maybe you are finding bugs in parallel with the coding and they are fixed before ever becoming “bug reports”. In that case, you did find bugs but are not giving yourself credit.
- You are not as excellent as you think. Sorry. Finding bugs might require skills you don’t have. Are you attempting to test data integrity without understanding the domain? Are you testing network transmissions without reading pcaps?
As testers, we often feel expendable when we don’t find bugs. We like to rally around battle cries like:
“If it ain’t broke, you’re not trying hard enough!”
“I don’t make software, I break it!”
“There’s always one more bug.”
But consider this, a skilled tester can do much more than merely find a bug. A skilled tester can also tells us what appears to work, what hasn’t broken in the latest version, what unanticipated changes have occurred in our product, how it might work better, how it might solve additional problems, etc.
And that may be just as important as finding bugs.
Invigorated by the comments in my last post, I’ll revisit the topic.
I don’t think we can increase our tester reputations by sticking to the credo:
“Raise every bug, no matter how trivial”
Notice, I’m using the language “raise” instead of “log”. This is an effort to include teams that have matured to the point of replacing bug reports with conversations. I used the term “share” in my previous post but I like “raise” better. I think Michael Bolton uses it.
Here are a couple problems with said credo:
- Identifying bugs is so complex that one cannot commit to raising them all. As we test, there are countless evaluations our brains are making; “That screen seems slow today, that control might be better a hair to the right, why isn’t there a flag in the DB to persist that data?”. We are constantly making decisions of which observations are worth spending time on. The counter argument to my previous post seems to be, just raise everything and let the stakeholders decide. I argue, everything is too much. Instead, the more experience and skill a tester gains, the better she will know what to raise. And yes, she should be raising a lot, documenting bugs/issues as quickly as she can. I still think, with skill, she can skip the trivial ones.
- Raising trivial bugs hurts your reputation as a tester. I facilitate bug triage meetings with product owners. Trivial bugs are often mocked before being rejected": “Ha! Does this need to be fixed because it’s bugging the tester or the user? Reject it! Why would anyone log that?”. Important bugs have the opposite reaction. Sorry. That’s the way it is.
- Time is finite. If I’m testing something where bugs are rare, I’ll be more inclined to raise trivial bugs. If I’m testing something where bugs are common, I’ll be more inclined to spend my time on (what I think) are the most important bugs.
It’s not the tester’s job to decide what is important. Yes, in general I agree. But I’m not dogmatic about this. Maybe if I share some examples of trivial bugs (IMO), it will help:
- Your product has an administrative screen that only can be used by a handful of tech support people. They use it once a year. As a tester, you notice the admin screen does not scroll with your scroll wheel. Instead, one must use the scroll bar. Trivial bug.
- Your product includes a screen with two radio buttons. You notice that if you toggle between the radio buttons 10 times and then try to close the screen less than a second later, a system error gets logged behind the scenes. Trivial bug.
- Your product includes 100 different reports users can generate. These have been in production for 5 years without user complaints. You notice some of these reports include a horizontal line above the footer while others do not. Trivial bug.
- The stakeholders have given your development team 1 million dollars to build a new module. They have expressed their expectations that all energy be spent on the new module and they do not want you working on any bugs in the legacy module unless they report the bug themselves and specifically request its fix. You find a bug in the legacy module and can’t help but raise it…
You laugh, but the drive to raise bugs is stronger than you may think. I would like to think there is more to our jobs than “Raise every bug, no matter how trivial”.
Don’t Tell Anyone About Trivial Bugs
17 comments Posted by Eric Jacobson at Friday, September 26, 2014(Edit on 10/1/2014) Although too long, a better title would have been “You May Not Want To Tell Anyone About That Trivial Bug”. Thanks, dear readers, for your comments.
It’s a bug, no doubt. Yes, you are a super tester for finding it. Pat yourself on the back.
Now come down off that pedestal and think about this. By any stretch of the imagination, could that bug ever threaten the value of the product-under-test? Could it threaten the value of your testing? No? Then swallow your pride and keep it to yourself.
My thinking used to be: “I’ll just log it as low priority so we at least know it exists”. As a manager, when testers came to me with trivial bugs, I used to give the easy answer, “Sure, they probably won’t fix it but log it anyway”.
Now I see things differently. If a trivial bug gets logged, often…
- a programmer sees the bug report and fixes it
- a programmer sees the bug report and wonders why the tester is not testing more important things
- a team member stumbles upon the bug report and has to spend 4 minutes reading it and understanding it before assigning some other attribute to it (like “deferred” or “rejected”)
- a team member argues that it’s not worth fixing
- a tester has spent 15 minutes documenting a trivial bug.
It seems to me, reporting trivial bugs tends to waste everybody’s time. Time that may be better spent adding value to your product. If you don’t buy that argument, how about this one: Tester credibility is built on finding good bugs, not trivial ones.
Don’t Bother Indicating “Pass” or “Fail”
1 comments Posted by Eric Jacobson at Tuesday, August 05, 2014This efficiency didn’t occur to me until recently. I was doing an exploratory test session and documenting my tests via Rapid Reporter. My normal process had always been to document the test I was about to execute…
TEST: Edit element with unlinked parent
…execute the test. Then write “PASS” or “FAIL” after it like this…
TEST: Edit element with unlinked parent – PASS
But it occurred to me that if a test appears to fail, I tag said failure as a “Bug”, “Issue”, “Question”, or “Next Time”. As long as I do that consistently, there is no need to add “PASS” or “FAIL” to the documented tests. While debriefing about my tests post session, the assumption will be that the test passed unless indicated otherwise.
Even though it felt like going to work without pants, after a few more sessions, it turns out, not resolving to “PASS” or “FAIL” reduces administrative time and causes no ambiguity during test reviews. Cool!
Wait. It gets better.
On further analysis, resolving all my tests to “PASS” or “FAIL” may have prevented me from actual testing. It was influencing me to frame everything as a check. Real testing does not have to result in “PASS” or “FAIL”. If I didn’t know what was supposed to happen after editing an element with an unlinked parent (as in the above example), well then it didn’t really “PASS” or “FAIL”, right? However, I may have learned something important nevertheless, which made the test worth doing…I’m rambling.
The bottom line is, maybe you don’t need to indicate “PASS” or “FAIL”. Try it.

So, you’ve got a green thumb. You’ve been growing houseplants your whole life. Now try to grow an orchid. What you’ve learned about houseplants has taught you very little about orchids.
- Put one in soil and you’ll kill it (orchids grow on rocks or bark).
- Orchids need about 20 degrees Fahrenheit difference between day and night.
- Orchids need wind and humidity to strive.
- Orchids need indirect sunlight. Lots of it. But put them in the sun and they’ll burn.
- Fading flowers does not mean your orchid is dying (orchids bloom in cycles).
So, you’re a skilled tester. You’ve been testing functional applications with user interfaces your whole career. Now try to test a data warehouse. What you’ve learned about functionality testing has taught you very little about data testing.
- “Acting like a user”, will not get you far. Efficient data testing does not involve a UI and depends little on other interfaces. There are no buttons to click or text boxes to interrogate during a massive data quality investigation.
- Lack of technical skills will kill you. Interacting with a DB requires DB Language skills (e.g., TSQL). Testing millions of lines of data requires coding skills to enlist the help of machine-aided-exploratory-testing.
- Checking the health of your data warehouse prior to deployments probably requires automated checks.
- For functional testing, executing shallow tests first to cover breadth, then deep tests later is normally a good approach. In data testing, the opposite may be true.
- If you are skilled at writing bug reports with detailed repro steps, this skill may hinder your effectiveness at communicating data warehouse bugs, where repro steps may not be important.
- If you are used to getting by as a tester, not reading books about the architecture or technology of your system-under-test, you may fail at data warehouse testing. In order to design valuable tests, a tester will need to study data warehouses until they grok concepts like Inferred Members, Junk Dimensions, Partitioning, Null handling, 3NF, grain, and Rapidly Changing Monster Dimensions.
Testers, let’s respect the differences in the projects we test, and grow our skills accordingly. Please don’t use a one-size-fits-all approach.
I think it’s only people who experience bugs.
Sadly, devs, BAs, other testers, stakeholders, QA managers, directors, etc. seldom appear interested in the fruits of our labor. The big exception is when any of these people experience a bug, downstream of our test efforts.
“Hey, did you test this? Did it pass? It’s not working when I try it.”
Despite the disinterest, us testers spend a lot of effort standing up ways to report test results. Whether it be elaborate pass/fail charts or low-tech information-radiators on public whiteboards, we do our best. I’ve put lots of energy into coaching my testers to give better test reports but I often second guess this…wondering how beneficial the skill is.
Why isn’t anyone listening? These are some reasons I can think of:
- Testers have done such a poor job of communicating test results, in the past, that people don’t find the results valuable.
- Testers have done such a poor job of testing, that people don’t find the results valuable.
- People are mainly interested in completing their own work. They assume all is well with their product until a bug report shows up.
- Testing is really difficult to summarize. Testers haven't found an effective way of doing this.
- Testing is really difficult to summarize. Potentially interested parties don’t want to take the time to understand the results.
- People think testers are quality cops instead of quality investigators; People will wait for the cops to knock on their door to deliver bad news.
- Everyone else did their own testing and already know the results.
- Test results aren’t important. They have no apparent bearing on success or failure of a product.
James Bach’s Beautiful Testing Metaphors
6 comments Posted by Eric Jacobson at Thursday, May 22, 2014(and one of Michael Bolton’s)
One of my testers took James Bach’s 3-day online Rapid Testing Intensive class. I poked my head in from time to time, couldn’t help it. What struck me is how metaphor after metaphor dripped from Bach’s mouth like poetry. I’ve heard him speak more times than I can count but I’ve never heard such a spontaneous panoply of beautiful metaphors. Michael Bolton, acting as assistant, chimed in periodically with his own metaphors. Here are some from the portions I observed:
- A tester is like a smoke alarm, their job is to tell people when and where a fire is. However, they are not responsible for telling people how to evacuate the building or put out the fire.
- (Michael Bolton) Testers are like scientists. But scientists have it easy; They only get one build. Testers get new builds daily so all bets are off on yesterday’s test results.
- Buying test tools is like buying a sweater for someone. The problem is, they feel obligated to wear the sweater, even if it’s not a good fit.
- Testers need to make a choice; either learn to write code or learn to be charming. If you’re charming, perhaps you can get a programmer to write code for you. It’s like having a friend who owns a boat.
- Deep vs. Shallow testing. Some testers only do Shallow testing. That is like driving a car with a rattle in the door…”I hear a rattle in the door but it seems to stay shut when I drive so…who cares?”.
- Asking a tester how long it will take to test is like being diagnosed with cancer and asking the doctor how long you have to live.
- Asking a tester how long the testing phase will last is like asking a flight attendant how long the flight attendant service will last.
- Complaining to the programmers about how bad their code looks is like being a patron at a restaurant and walking back into the kitchen to complain about the food to the chefs. How do you think they’re going to take it?
- Too many testers and test managers want to rush to formality (e.g., test scripts, test plans). It’s like wanting to teleport yourself home from the gym. Take the stairs!
Questioning Tester Assumptions With Alex Kell
1 comments Posted by Eric Jacobson at Friday, May 09, 2014Last week, Alex Kell (Atlanta-based tester and my former boss) gave a fun talk at Software Testing Club Atlanta, ”The Oracle is Fallible: Recognizing, Understanding, and Evaluating the Assumptions that Testers Make”.
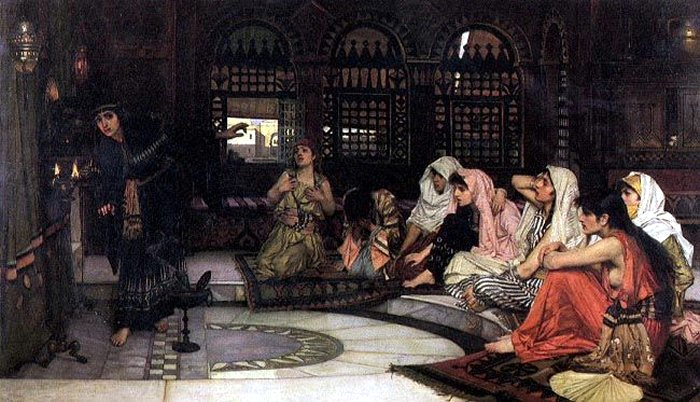
Here are the highlights from my notes:
- After showing John William Waterhouse’s famous 1884 painting, Consulting the Oracle (above), of 7 priestesses listening to an 8th priestess (playing the Oracle) interpret from the gods, Alex asked:
- “Assumptions, are they bad or good?”
- We make them because we’re lazy.
- Sometimes we know we’re making an assumption, sometimes we don’t know.
- After some discussion and examples of assumptions we realized we are all constantly making assumptions every waking moment and decided assumptions can be good or bad.
- Bad assumptions (or forgetting the Oracle is fallible):
- “The spec is correct.” – Be careful. Remember Ron Jeffries “Three Cs”:
- The Spec (AKA “Card”) is a reminder to have a conversation about something.
- The Conversation is a discussion of the details that result in test confirmations.
- The Confirmation is acceptance criteria that can be turned into acceptance tests.
- “They know what they’re doing.” – What if everybody on the team is thinking this…group think?
- “I know what I’m doing.”
- “The software is working because we haven't seen a (red) failed test.” (Dennis Stevens says “Every project starts red, and it stays red, until it is green.”)
- “The model is reality.” – A model is an abstraction. All decisions based on models are based on assumptions. You should never be surprised when a model does not turn out to reflect reality. Author, Nassim Nicholas Taleb, coined the word “platonicity” to describe the human tendency to find patterns in everything.
Alex gave a nearly literal example of where people fall victim to this bad assumption: He told of people on Craig’s List (or similar) paying money for things like actual cars one can drive, only to discover they had just purchased a scaled down model of a car. - Good assumptions (I loved this and thought it was pretty bold to declare some assumptions being good for testers):
- “The estimates are accurate”. – Take what you did last time. Use the estimate until it is no longer helpful.
- “The web service will honor its contract”. If testers didn’t make this assumption, might they be wasting time testing the wrong thing?
- There were more good assumptions but I have a gap in my notes. Maybe Alex will leave a comment with those I missed.
- Alex talked about J.B. Rainsberger’s “Integrated Tests Are a Scam” – In other words, if we don’t make some assumptions, we would have to code tests for the rest of our lives to make a dent in our coverage.
- Suggestions to deal with assumptions:
- Be explicit about your assumptions.
- Use truth tables for complex scenarios (Alex shared one he used for his own testing).
- System thinking – Testers should be able to explain the whole system. This cuts down on bad assumptions.
Aren’t You Glad You’re a Software Tester?
2 comments Posted by Eric Jacobson at Friday, March 28, 2014It’s true. Our job rocks. Huff Post called it the 2nd happiest job in America this year. Second only to being a DBA…yawn. Two years ago, Forbes said testing was #1.
But why? Neither article goes in depth. Maybe it’s because all news is good news, for a tester:
- The System Under Test (SUT) is crashing in QA, it doesn’t work, it’s a steaming pile of…YES! My testing was valuable! My life has meaning! My testing just saved users from this nightmare!
- The SUT is finally working. Awesome! It’s so nice being part of a development team that can deliver quality software. I can finally stop testing it and move on. Our users are going to love this.
See? Either way it’s good news.
Or maybe I just spin it that way to love my job more. So be it. If you think your testing job is stressful, you may want to make a few adjustments in how you work. Read my You’re a Tester, Relax post.
When Poor Test Documentation Hurts
5 comments Posted by Eric Jacobson at Thursday, December 19, 2013I would much rather test than create test documents. Adam White once told me, “If you’re not operating the product, you’re not testing”.
It’s soooooo easy to skip all documentation and dive right in to the testing. It normally results in productive testing and nobody misses the documents. Until…three years later, when the prog makes a little change to a module that hasn’t been tested since. The team says the change is high risk and asks you which tests you executed three year ago and how long it took.
Fair questions. I think we, as testers, should be able to answer. Even the most minimal test documentation (e.g., test fragments written in notepad) should be able to answer those questions.
If we can’t answer relatively quickly, we may want to consider recording better test documentation.
…are not always the full truth. Is that hurting our craft?
Last week, I attended the first Software Testing Club Atlanta Meetup. It was organized by Claire Moss and graciously hosted by VersionOne. The format was Lean Coffee, which was perfect for this meeting.

Photo by Claire Moss
I’m not going to blog about the discussion topics themselves. Instead, I would like to blog about a familiar Testing Story pattern I noticed:
During the first 2 hours, it seemed to me, we were telling each other the testing stories we wanted to believe, the stories we wanted each other to believe. We had to make first impressions and establish our personal expertise, I guess. But during the 3rd hour, we started to tell more candid stories, about our testing struggles and dysfunctions. I started hearing things like, “we know what we should be doing, we just can’t pull it off”. People who, at first impression, seemed to have it all together, seemed a little less intimidating now.
When we attend conference talks, read blog posts, and socialize professionally, I think we are in a bubble of exaggerated success. The same thing happens on Facebook, right? And people fall into a trap: The more one uses Facebook, the more miserable one feels. I’m probably guilty of spreading exaggerated success on this blog. I’m sure it’s easier, certainly safer, to leave out the embarrassing bits.
That being said, I am going to post some of my recent testing failure stories on this blog in the near future. See you soon.
Multiple Computers Are a Must For Testers
6 comments Posted by Eric Jacobson at Monday, September 30, 2013I can’t imagine testing without multiple computers at my disposal. You may want to hold on to your old, out of warranty computers if given the choice. Five quick reasons:
- When Computer#1 hits an impediment such as an unrecoverable error, Computer#2 can start testing immediately as Computer#1 reboots.
- I can use both computers to simulate interesting multi-user tests. Example: what if two users attempt to acquire locks at roughly the same time.
- I can kick off timely processes, staggered on 3 separate boxes, so as not to sit idle waiting.
- Different OS’s, browser versions, frameworks, and other software running in the background can be informally tested to narrow down variables.
- Computer#1 can support the administrative work of testing (e.g., documenting tests, bugs, emailing), while Computer#2 can stay clean and focus on operating the product under test.
Why Integration Testing is Difficult
6 comments Posted by Eric Jacobson at Wednesday, September 18, 2013What is the relationship between these two objects?


How about these two?


This, I’m afraid, is how testers (myself included) often see software modules…like black boxes. Their relationships are hidden from us. We know the programmer just changed something related to the seeds inside the orange, so we ask ourselves, “How could changing the seeds inside the orange affect the toaster?”. Hmmmm. “Well, it sure seems like it couldn’t”. Then, after a deployment, we’re shocked to discover the toaster starts burning all the toast.
Why didn’t the programmer warn us? Well, just because the programmer understands the innards of the orange, doesn’t mean they understand the innards of the toaster. In fact, based on my experiences, if there is enough work to do on the orange, the orange programmer will happily take it over learning to code for the toaster.
So here we are, left with nothing better to do than regression test the toaster, the jointer, and the flash light, every time the orange changes. No wonder we spend so much time regression testing.
In conclusion, maybe the more we learn about the architecture behind our software system, the fewer regression tests we’ll need to execute. Instead, we’ll better focus our testing and make the invisible relationships visible for the rest of the team…before development even begins.
- Spend time reporting problems that already exist in production, that users have not asked to fix.
- Demand all your bugs get fixed, despite the priorities of others.
- Keep your test results to yourself until you’re finished testing.
- Never consider using test tools.
- Attempt to conduct all testing yourself, without asking non-testers for help.
- Spend increasingly more time on regression tests each sprint.
- Don’t clean up your test environments.
- Keep testing the same way you’ve always tested. Don’t improve your skills.
- If you need more time to test it, ask to have it pulled from the sprint, you can test it during the next sprint.
- Don’t start testing until your programmer tells you “okay, it’s ready for testing”.
If you made two lists for a given software feature (or user story):
- all the plausible user scenarios you could think of
- all the implausible user scenarios you could think of
…which list would be longer?
I’m going to say the latter. The user launches the product, holds down all the keys on the keyboard for four months, removes all the fonts from their OS, then attempts to save a value at the exact same time as one million other users. One can determine implausible user scenarios without obtaining domain knowledge.
Plausible scenarios should be easier to predict, by definition. It may be that only one out of 100 users stray from the “happy path”, in which case our product may have just experienced an implausible scenario.
What does this have to do with testing? As time becomes dearer, I continue to refine my test approach. It seems to me, the best tests to start with are still confirmatory (some call these “happy path”) tests. There are fewer of them, which makes it more natural to know when to start executing the tests for the scenarios less likely to occur.

The chart above is my attempt to illustrate the test approach model I have in my head. The Y axis is how plausible the test is (e.g., it is 100% likely that users will do this, it is 50% likely that users will do this). The X axis represents the test order (e.g., 1st test executed, 2nd test executed, etc.). The number of tests executed is relative.
Basically, I start with the most plausible tests, then shift my focus to the stuff that will rarely happen. These rare scenarios at the bottom of the chart above can continue forever as you move toward 0% plausibility, so I generally use the “Times Up” stopping heuristic. One can better tackle testing challenges with this model if one makes an effort to determine how users normally use the product.
I often hear contradictory voices in my head saying, “don’t start with confirmatory tests, the bugs are off the beaten path”. Okay, but are they really? If our definition of a bug is “something that bugs someone who matters”, then the problems I find on the bottom of the above chart’s line, may matter less than those found on the top. Someone who matters, may not venture to the bottom.
For more on my thoughts (and contrary thoughts) on this position see We Test To Find Out If Software *Can* Work.
 RSS